How does Google's Gemini 4 train its model ? Trillion-Token Scale, Reasoning and Synthetic Data
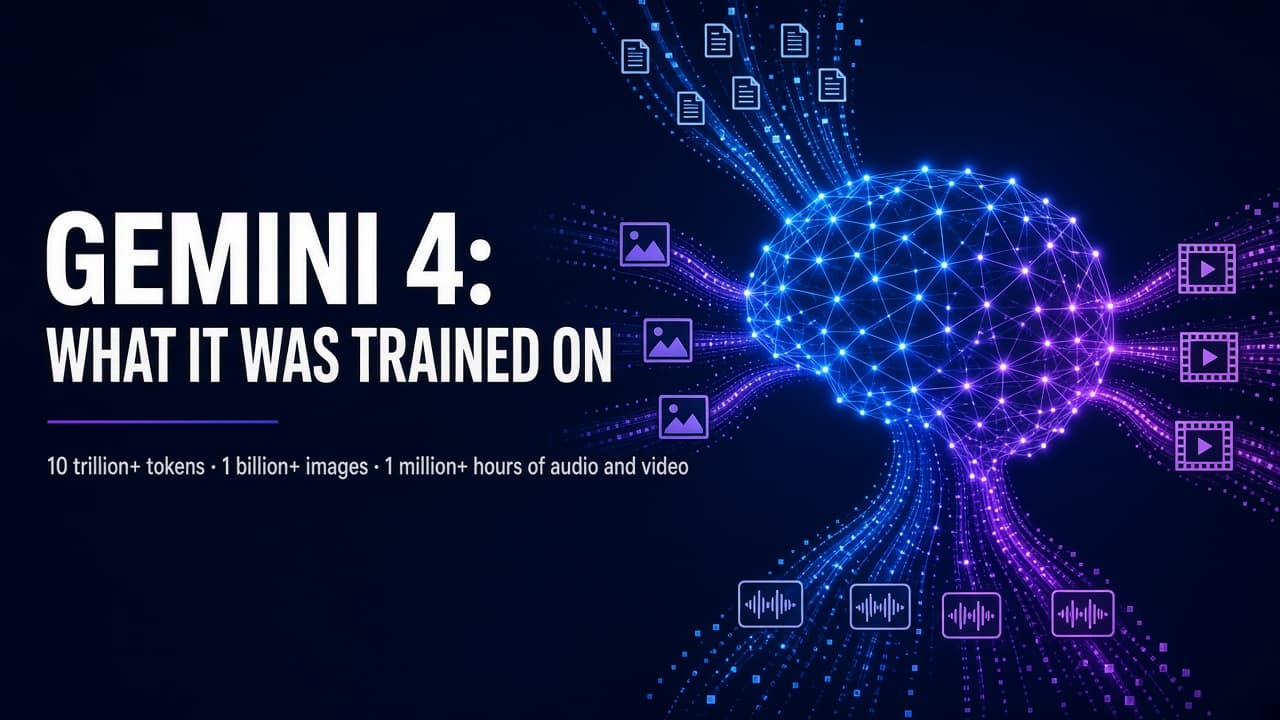
Google's EU Public Summary of Training Content (updated 13 October 2026) says the Gemini 4 family was trained on more than 10 trillion text tokens, over 1 billion images and over 1 million hours each of audio and video. It reveals reinforcement learning for reasoning and theorem-proving in Gemini 4 Argon, synthetic data from Gemini 3, Gemini Apps user chats, and robots.txt and Google-Extended controls, with no country breakdown.
Google has disclosed that its Gemini 4 family of models was trained on more than 10 trillion text tokens, more than one billion images, and more than one million hours each of audio and video, and its disclosure gives a rare look inside the training pipeline behind them.
The eight-page Public Summary of Training Content, filed by Google Ireland Limited and last updated on 13 October 2026, covers the Gemini 4 family, which the document says was placed on the European Union market in October 2026.
The scale of the training data
- Text: more than 10 trillion tokens
- Images: more than 1 billion images
- Audio: more than 1 million hours
- Video: more than 1 million hours
These are the highest disclosure bands on the form, not exact totals.
"More than 10 trillion tokens" sets a floor and no ceiling.
Tokens are the units a model uses to process text and code; they are not words, documents or users.
The flagship model, Gemini 4 Argon, is described as not a modification or fine-tune of a prior model.
Its knowledge cut-off is March 2026, although Google says it may update models after that date.
Two training stages: pre-training and post-training
Pre-training used a large, diverse collection of publicly available web documents, code, images, audio including speech, and video.
Text sources include software code and documents from educational, government, legal and research sectors, as well as open-source data and code repositories.
Post-training used three kinds of data: instruction-tuning data, reinforcement learning data and human-preference data.
Google says Gemini 4 Argon was trained using reinforcement learning techniques that can leverage multi-step reasoning, problem-solving and theorem-proving data, pointing to a deliberate focus on structured reasoning and mathematical proof rather than next-word prediction alone.
Google also says it obtained non-public datasets from third parties covering educational materials, scientific reasoning and mathematics, separate from datasets licensed commercially from rightsholders.
AI training AI: how the synthetic data was made
Google confirms that Gemini 4 was partly trained on synthetic data generated by its own earlier Gemini 3 family, along with fine-tuned versions of internal models and non-general-purpose models.
The report names the methods as prompting and response editing across a range of targeted capabilities: older models generated examples aimed at specific skills, which were then edited before being used for training.
Synthetic data covered text, images and audio; video is not checked for synthetic data.
Inside the crawler pipeline
Google says its crawlers are used to discover and scan websites, build its search indexes, perform product-specific crawls and carry out analysis.
The training summary points to this same crawler infrastructure rather than describing a separate AI-only crawler.
According to the report, Google's common crawlers obey robots.txt rules when crawling automatically, a statement limited to that crawler category.
A separate Google-Extended control lets publishers decide whether content Google crawls from their sites may be used for training and grounding.
Google also publishes information that lets site operators verify whether a request genuinely comes from Google, relevant because crawler identities can be spoofed.
The crawled material spans .com, .org, .edu and international country-code domains.
Crawled data is marked as covering text, images and audio, but not video, even though video appears elsewhere among the overall training sources.
User chats and internal data
Google says it uses data collected from users of its products and services, including user chats with Gemini Apps, to train AI models, in accordance with its terms of service, privacy policy, service-specific policies and user controls where appropriate.
The report does not say what share of training data came from user interactions, and it does not establish that every user's chats were included.
A further category covers data Google acquires or generates in the course of its business operations, or directly from its workforce.
Filtering before training
Before training, Google says it applied deduplication, quality filtering, robots.txt compliance and safety filtering.
The filtering may remove harmful text and other material, including content that is pornographic, violent or violative of child sexual abuse material laws.
Google also confirms it is a signatory to the EU general-purpose AI Code of Practice, which includes commitments to respect rights reservations under text and data mining rules.
These are Google's own descriptions of its processes, not an independent audit, and no figures are given for how much material was filtered out.
What remains unknown
The report does not list individual websites, books, datasets or conversations.
It does not say how much each source contributed, give exact data volumes or provide any country-level breakdown, including for India.
Its European regulatory context does not mean the training data came only from Europe.
The report says the models were trained on a breadth of languages, including EU official languages, "representative of the internet in general."
Source: Google's Public Summary of Training Content for the Gemini 4 family, updated 13 October 2026.